Run locally
git clone https://github.com/qchiujunhao/whatran
cd whatran/examples/cancer-classification
bash run.shGenerated example · fresh-clone checked
Can tumor measurements separate malignant from benign, and is that conclusion stable across a linear and a nonlinear model?
Logistic regression ranked first by highest mean five-fold training-set CV ROC AUC.
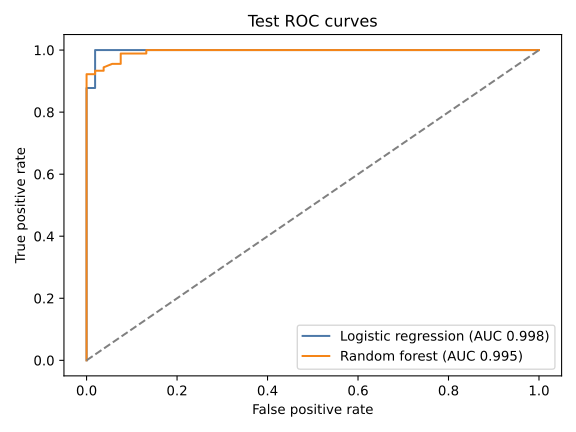
Both retained model families exceeded the prespecified 0.95 cross-validation ROC AUC threshold. The selected path is highlighted, while both remain part of the final report.
| Metric | Logistic regression Selected | Random forest |
|---|---|---|
| Accuracy | 0.986 | 0.958 |
| F1 score | 0.989 | 0.967 |
| Test ROC AUC | 0.998 | 0.995 |
| Five-fold CV ROC AUC | 0.996 ± 0.004 | 0.989 ± 0.010 |
Cross-validation ROC AUC range: 0.007; test ROC AUC range: 0.003.
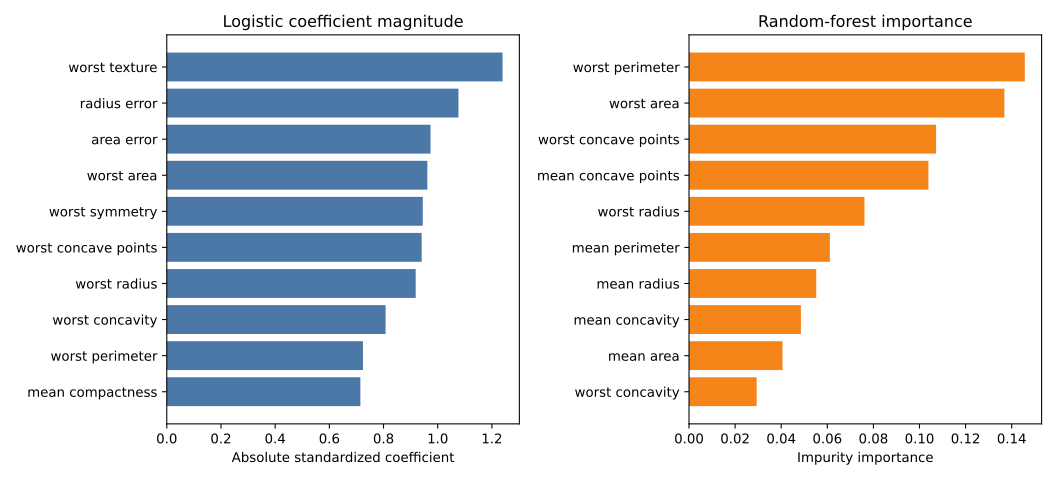
Every result-affecting script is present in execution order. Source is collapsed by default so the finding stays readable, but nothing needed for the rerun is hidden.
Produces: train.csv, test.csv
#!/usr/bin/env python3
"""Step 1 — load the raw data and make a seeded, stratified train/test split."""
from __future__ import annotations

import pandas as pd
from sklearn.model_selection import train_test_split

RAW = "data/cancer.csv"
SEED = 42
TEST_SIZE = 0.25


def main() -> None:
    df = pd.read_csv(RAW)
    features = df.drop(columns=["target"])
    target = df["target"]
    x_train, x_test, y_train, y_test = train_test_split(
        features, target, test_size=TEST_SIZE, random_state=SEED, stratify=target
    )
    train = x_train.assign(target=y_train)
    test = x_test.assign(target=y_test)
    train.to_csv("results/train.csv", index=False)
    test.to_csv("results/test.csv", index=False)
    print(f"train {train.shape} test {test.shape}")


if __name__ == "__main__":
    main()
Produces: logistic_metrics.json, logistic_roc.json, logistic_coefficients.json
#!/usr/bin/env python3
"""Path A — standardized logistic regression on the shared split."""
from __future__ import annotations

import json

import pandas as pd
from sklearn.linear_model import LogisticRegression
from sklearn.metrics import (
    accuracy_score,
    f1_score,
    precision_score,
    recall_score,
    roc_auc_score,
    roc_curve,
)
from sklearn.model_selection import StratifiedKFold, cross_val_score
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

SEED = 42


def main() -> None:
    train = pd.read_csv("results/train.csv")
    test = pd.read_csv("results/test.csv")
    x_train, y_train = train.drop(columns=["target"]), train["target"]
    x_test, y_test = test.drop(columns=["target"]), test["target"]

    model = make_pipeline(
        StandardScaler(),
        LogisticRegression(solver="liblinear", max_iter=5000, random_state=SEED),
    )
    model.fit(x_train, y_train)
    probability = model.predict_proba(x_test)[:, 1]
    prediction = (probability >= 0.5).astype(int)

    folds = StratifiedKFold(n_splits=5, shuffle=True, random_state=SEED)
    cv_scores = cross_val_score(
        model, x_train, y_train, cv=folds, scoring="roc_auc", n_jobs=1
    )
    metrics = {
        "path": "logistic_regression",
        "positive_class": "benign",
        "seed": SEED,
        "n_train": int(len(y_train)),
        "n_test": int(len(y_test)),
        "accuracy": round(float(accuracy_score(y_test, prediction)), 6),
        "precision": round(float(precision_score(y_test, prediction)), 6),
        "recall": round(float(recall_score(y_test, prediction)), 6),
        "f1": round(float(f1_score(y_test, prediction)), 6),
        "roc_auc": round(float(roc_auc_score(y_test, probability)), 6),
        "cv_roc_auc_mean": round(float(cv_scores.mean()), 6),
        "cv_roc_auc_std": round(float(cv_scores.std()), 6),
    }
    with open("results/logistic_metrics.json", "w", encoding="utf-8") as handle:
        json.dump(metrics, handle, indent=2, sort_keys=True)
        handle.write("\n")

    false_positive, true_positive, _ = roc_curve(y_test, probability)
    roc = [
        {"false_positive_rate": round(float(x), 10), "true_positive_rate": round(float(y), 10)}
        for x, y in zip(false_positive, true_positive)
    ]
    with open("results/logistic_roc.json", "w", encoding="utf-8") as handle:
        json.dump(roc, handle, indent=2)
        handle.write("\n")

    coefficients = model.named_steps["logisticregression"].coef_[0]
    drivers = sorted(
        (
            {
                "feature": feature,
                "coefficient": round(float(value), 10),
                "magnitude": round(abs(float(value)), 10),
            }
            for feature, value in zip(x_train.columns, coefficients)
        ),
        key=lambda row: (-row["magnitude"], row["feature"]),
    )
    with open("results/logistic_coefficients.json", "w", encoding="utf-8") as handle:
        json.dump(drivers, handle, indent=2)
        handle.write("\n")

    print("logistic metrics:", metrics)


if __name__ == "__main__":
    main()
Produces: forest_metrics.json, forest_roc.json, forest_importance.json
#!/usr/bin/env python3
"""Path B — seeded random forest on the shared split."""
from __future__ import annotations

import json

import pandas as pd
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import (
    accuracy_score,
    f1_score,
    precision_score,
    recall_score,
    roc_auc_score,
    roc_curve,
)
from sklearn.model_selection import StratifiedKFold, cross_val_score

SEED = 42


def main() -> None:
    train = pd.read_csv("results/train.csv")
    test = pd.read_csv("results/test.csv")
    x_train, y_train = train.drop(columns=["target"]), train["target"]
    x_test, y_test = test.drop(columns=["target"]), test["target"]

    model = RandomForestClassifier(n_estimators=200, random_state=SEED, n_jobs=1)
    model.fit(x_train, y_train)
    probability = model.predict_proba(x_test)[:, 1]
    prediction = (probability >= 0.5).astype(int)

    folds = StratifiedKFold(n_splits=5, shuffle=True, random_state=SEED)
    cv_scores = cross_val_score(
        model, x_train, y_train, cv=folds, scoring="roc_auc", n_jobs=1
    )
    metrics = {
        "path": "random_forest",
        "positive_class": "benign",
        "seed": SEED,
        "n_train": int(len(y_train)),
        "n_test": int(len(y_test)),
        "accuracy": round(float(accuracy_score(y_test, prediction)), 6),
        "precision": round(float(precision_score(y_test, prediction)), 6),
        "recall": round(float(recall_score(y_test, prediction)), 6),
        "f1": round(float(f1_score(y_test, prediction)), 6),
        "roc_auc": round(float(roc_auc_score(y_test, probability)), 6),
        "cv_roc_auc_mean": round(float(cv_scores.mean()), 6),
        "cv_roc_auc_std": round(float(cv_scores.std()), 6),
    }
    with open("results/forest_metrics.json", "w", encoding="utf-8") as handle:
        json.dump(metrics, handle, indent=2, sort_keys=True)
        handle.write("\n")

    false_positive, true_positive, _ = roc_curve(y_test, probability)
    roc = [
        {"false_positive_rate": round(float(x), 10), "true_positive_rate": round(float(y), 10)}
        for x, y in zip(false_positive, true_positive)
    ]
    with open("results/forest_roc.json", "w", encoding="utf-8") as handle:
        json.dump(roc, handle, indent=2)
        handle.write("\n")

    drivers = sorted(
        (
            {
                "feature": feature,
                "importance": round(float(value), 10),
            }
            for feature, value in zip(x_train.columns, model.feature_importances_)
        ),
        key=lambda row: (-row["importance"], row["feature"]),
    )
    with open("results/forest_importance.json", "w", encoding="utf-8") as handle:
        json.dump(drivers, handle, indent=2)
        handle.write("\n")

    print("forest metrics:", metrics)


if __name__ == "__main__":
    main()
Produces: comparison.json
#!/usr/bin/env python3
"""Compare the two retained paths and state the shared conclusion."""
from __future__ import annotations

import json
from pathlib import Path

STRONG_AUC = 0.95


def read_json(path: str) -> dict[str, object]:
    return json.loads(Path(path).read_text(encoding="utf-8"))


def main() -> None:
    paths = {
        "logistic_regression": read_json("results/logistic_metrics.json"),
        "random_forest": read_json("results/forest_metrics.json"),
    }
    selected = max(paths, key=lambda name: float(paths[name]["cv_roc_auc_mean"]))
    cv_values = [float(metrics["cv_roc_auc_mean"]) for metrics in paths.values()]
    test_values = [float(metrics["roc_auc"]) for metrics in paths.values()]
    stable = all(value >= STRONG_AUC for value in cv_values)

    comparison = {
        "comparison_basis": "highest mean five-fold training-set CV ROC AUC",
        "selected_path": selected,
        "strong_auc_threshold": STRONG_AUC,
        "both_paths_reach_threshold": stable,
        "cv_roc_auc_range": round(max(cv_values) - min(cv_values), 6),
        "test_roc_auc_range": round(max(test_values) - min(test_values), 6),
        "conclusion": (
            "Both model families support strong separation."
            if stable
            else "The separation conclusion depends on the model path."
        ),
        "paths": paths,
    }
    with open("results/comparison.json", "w", encoding="utf-8") as handle:
        json.dump(comparison, handle, indent=2, sort_keys=True)
        handle.write("\n")

    print("comparison:", comparison["conclusion"], "selected:", selected)


if __name__ == "__main__":
    main()
Produces: roc_comparison.svg, model_drivers.svg
#!/usr/bin/env python3
"""Visualize both retained model paths from their checked backing data."""
from __future__ import annotations

import json
from pathlib import Path

import matplotlib

matplotlib.use("Agg")
matplotlib.rcParams["svg.hashsalt"] = "whatran"
import matplotlib.pyplot as plt  # noqa: E402


def read_json(path: str) -> object:
    return json.loads(Path(path).read_text(encoding="utf-8"))


def save_svg(fig: object, path: str) -> None:
    fig.savefig(path, metadata={"Date": None})
    output = Path(path)
    output.write_text(
        "\n".join(line.rstrip() for line in output.read_text(encoding="utf-8").splitlines()) + "\n",
        encoding="utf-8",
    )


def main() -> None:
    comparison = read_json("results/comparison.json")
    logistic_roc = read_json("results/logistic_roc.json")
    forest_roc = read_json("results/forest_roc.json")

    fig, ax = plt.subplots(figsize=(6, 4.5))
    for label, points, color in (
        ("Logistic regression", logistic_roc, "#4c78a8"),
        ("Random forest", forest_roc, "#f58518"),
    ):
        metrics = comparison["paths"][
            "logistic_regression" if label.startswith("Logistic") else "random_forest"
        ]
        ax.plot(
            [point["false_positive_rate"] for point in points],
            [point["true_positive_rate"] for point in points],
            label=f"{label} (AUC {metrics['roc_auc']:.3f})",
            color=color,
        )
    ax.plot([0, 1], [0, 1], "--", color="gray")
    ax.set(xlabel="False positive rate", ylabel="True positive rate", title="Test ROC curves")
    ax.legend(loc="lower right")
    fig.tight_layout()
    save_svg(fig, "results/roc_comparison.svg")
    plt.close(fig)

    logistic = read_json("results/logistic_coefficients.json")[:10][::-1]
    forest = read_json("results/forest_importance.json")[:10][::-1]
    fig, axes = plt.subplots(1, 2, figsize=(11, 5))
    axes[0].barh(
        [row["feature"] for row in logistic],
        [row["magnitude"] for row in logistic],
        color="#4c78a8",
    )
    axes[0].set(title="Logistic coefficient magnitude", xlabel="Absolute standardized coefficient")
    axes[1].barh(
        [row["feature"] for row in forest],
        [row["importance"] for row in forest],
        color="#f58518",
    )
    axes[1].set(title="Random-forest importance", xlabel="Impurity importance")
    fig.tight_layout()
    save_svg(fig, "results/model_drivers.svg")
    plt.close(fig)

    print("wrote results/roc_comparison.svg and results/model_drivers.svg")


if __name__ == "__main__":
    main()
The repository carries the raw input, pinned Python environment, reference results, comparison policy, and one canonical rerun command.
git clone https://github.com/qchiujunhao/whatran
cd whatran/examples/cancer-classification
bash run.sh